A Multimodal Multi-Task Transformer for Emotion Understanding from Videos
Ádám Fodor, Kristian Fenech
Abstract
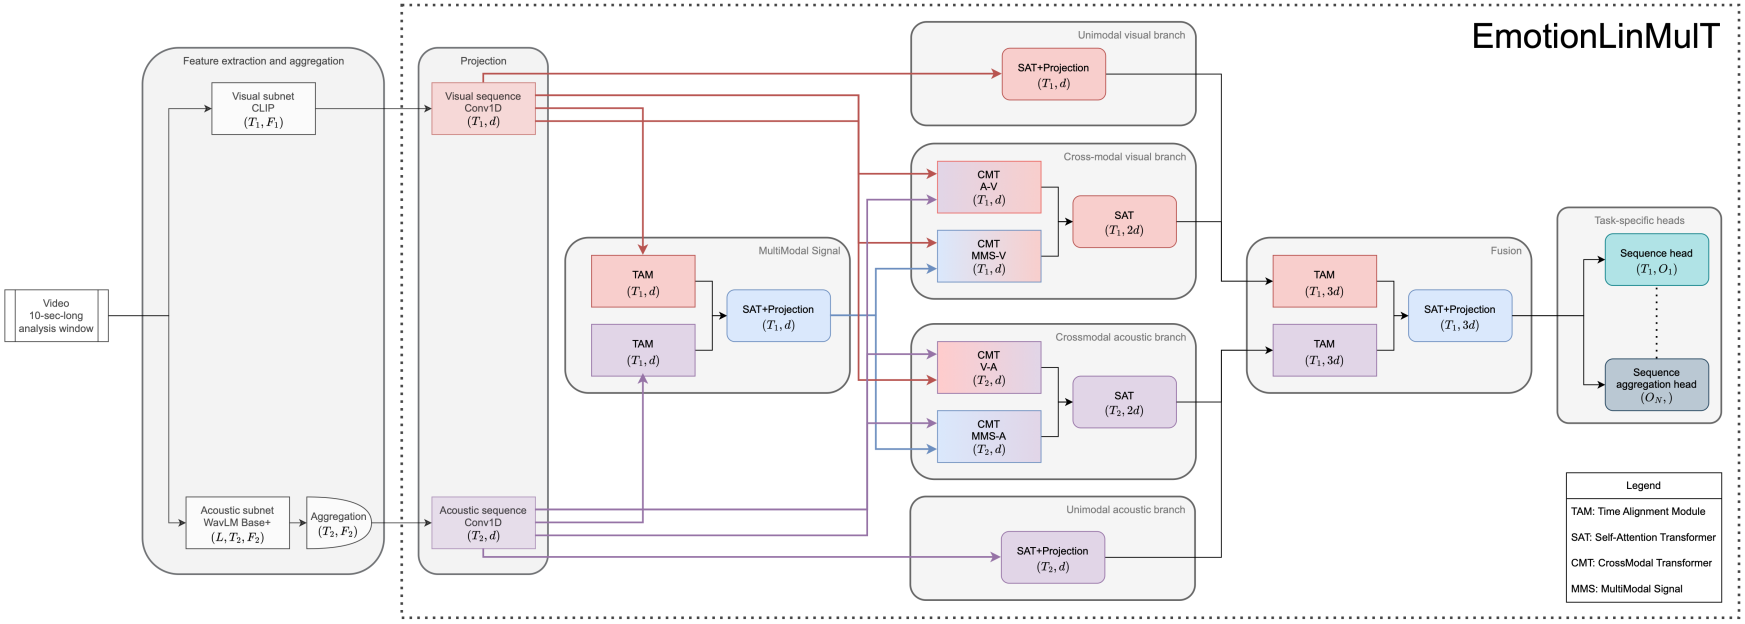
We present EmotionLinMulT, a compact multimodal, multi-task transformer for emotion understanding from video. It jointly predicts categorical emotions, intensity, valence, arousal, and sentiment using CLIP-based visual and WavLMbased audio features. The model is efficient through linear attention, enabling near-real-time processing. Trained and evaluated on diverse, disjoint datasets including AFEW-VA, AffWild2, CREMA-D, RAVDESS, and MOSEI, it delivers competitive results despite its small size. EmotionLinMulT is also designed to be robust to missing modalities, varied camera angles, and occlusion. While the model is well-suited for interactive human-centered applications, its general architecture also enables easy adaptation to a wide range of sequence related tasks.
The project is currently ongoing and progressing well.
I am actively working on this project and am excited about the promising results emerging so far. Once the work reaches the next milestone and the paper is submitted for publication, I will be able to share a comprehensive update with all the details and key findings. Thank you for your interest and support—please stay tuned for more information coming soon!
A poster presented at Hungarian Machine Learning Days can be checked in the gallery: Poster