personality_questionnaire
Administer, score and record validated personality and affect questionnaires.




What this is
Collecting validated self-reports is the unglamorous half of an affective-computing pipeline. This package administers published psychometric instruments, scores them correctly, and records every response with the provenance needed to reproduce the score months later.
It is built around one idea: an instrument is data, not code. Items, response ranges, subscale membership and reverse keys are declared as values; a single vectorised scorer turns responses into scores without knowing which questionnaire it is holding. Adding an instrument adds no arithmetic.
Instruments
Key |
Instrument |
Items |
Scale |
Scores |
|---|---|---|---|---|
|
Big Five Inventory-2 |
60 |
1–5 |
5 domains, 15 facets |
|
BFI-2 Extra-Short Form |
15 |
1–5 |
5 domains |
|
Big Five Inventory-10 |
10 |
1–5 |
5 domains |
|
Positive and Negative Affect Schedule |
20 |
1–5 |
Positive/Negative Affect |
|
Visual Analogue Scale to Evaluate Fatigue Severity |
18 |
0–10 |
Fatigue, Energy, composite |
BFI-2 and BFI-2-XS: Soto & John (2017). BFI-10: Rammstedt & John (2007). PANAS: Watson, Clark & Tellegen (1988). VAS-F: Lee, Hicks & Nino-Murcia (1991). See docs/instruments.md for full citations and licence notes.
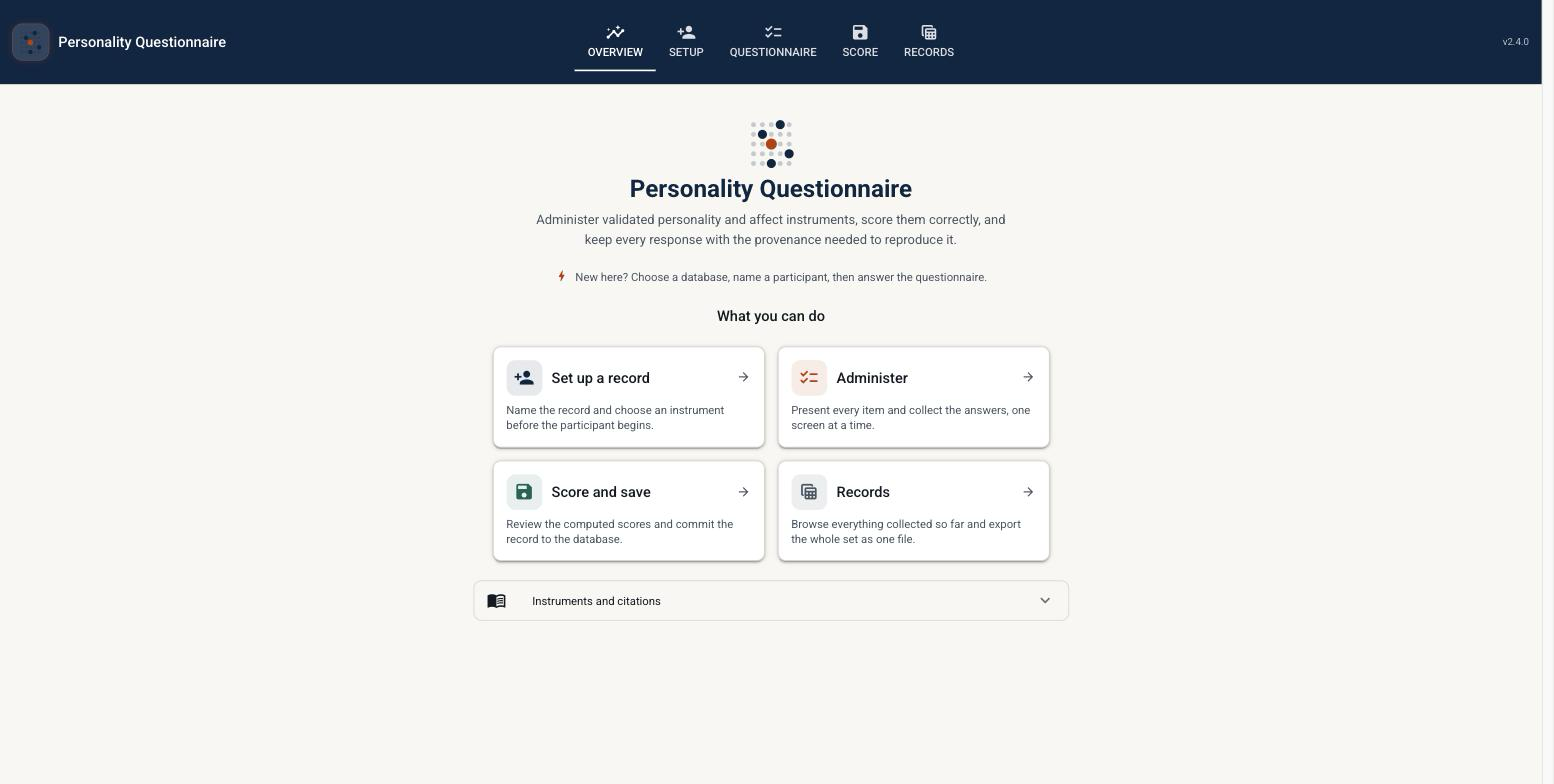
Landing page of the Personality Questionnaire application:
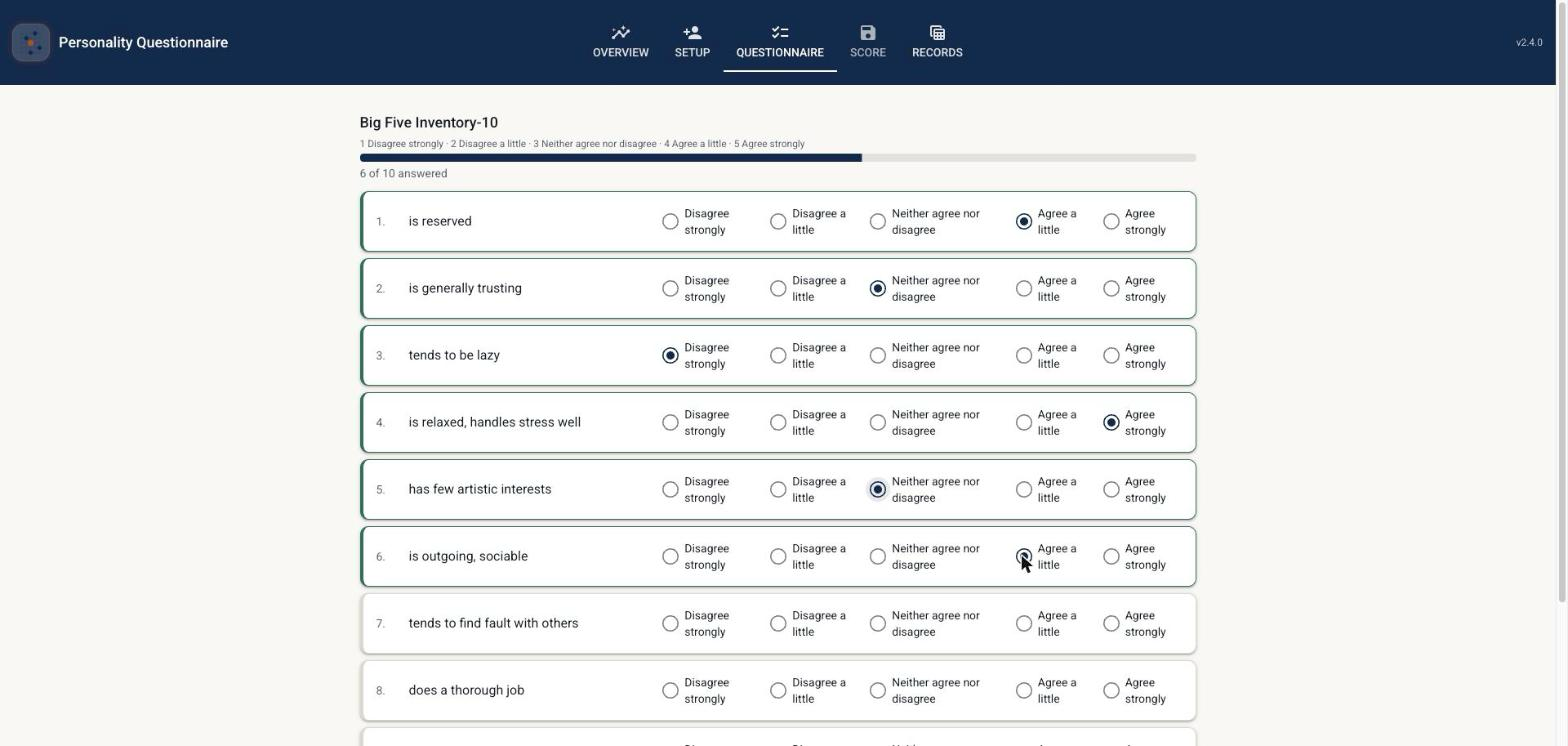
BFI-10 loaded on the Questionnaire tab:
Quickstart
Score responses you already have:
pip install personality_questionnaire
import personality_questionnaire as pq

result = pq.score(pq.get("bfi2"), answers)  # answers: (n_participants, 60)
result.by_level("domain")  # {"openness": array([...]), ...}
result.as_dict()  # one participant, every subscale
Administer one at the terminal:
pq list                                  # what is available
pq info bfi2                             # items, subscales, citation
pq run bfi2 --participant P01            # ask, score, and store
pq score bfi2 --input answers.csv        # score a file
Collect and export a study:
pip install "personality_questionnaire[ui]"          # adds the record store
pq run bfi2 --participant P01 --experiment study-a
pq records                                            # what is stored
pq export --shape long --output study-a.csv
Records go to ~/.personality_questionnaire/records.db unless PQ_DATABASE_URL
says otherwise. See docs/storage.md.
Or collect through the application, which binds to localhost and never reaches the network:
pq ui # http://127.0.0.1:8080
Five tabs: an overview, setup, the questionnaire itself, the computed scores, and every record collected so far with its exports. See docs/ui.md.
Try it without installing anything
A separate, stateless demo – pick an instrument, answer it, see the scores plotted (a radar for the Big Five forms, a bar chart for PANAS and VAS-F). Nothing entered is stored. Local-first is the primary, supported way to run it – both Hugging Face Space deployments below exist as optional extras and currently sit unpublished (see note).
Gradio version (demo/ – never imports the database layer above, and
tests/demo_app/test_isolation.py enforces that at CI time, not just in
prose):
pip install "personality_questionnaire[demo]"
pq demo        # http://127.0.0.1:7860
React/TypeScript version (demo-react/ – scoring reimplemented in
TypeScript rather than running Python client-side; see
docs/design.md for why):
make react-demo # http://localhost:5173
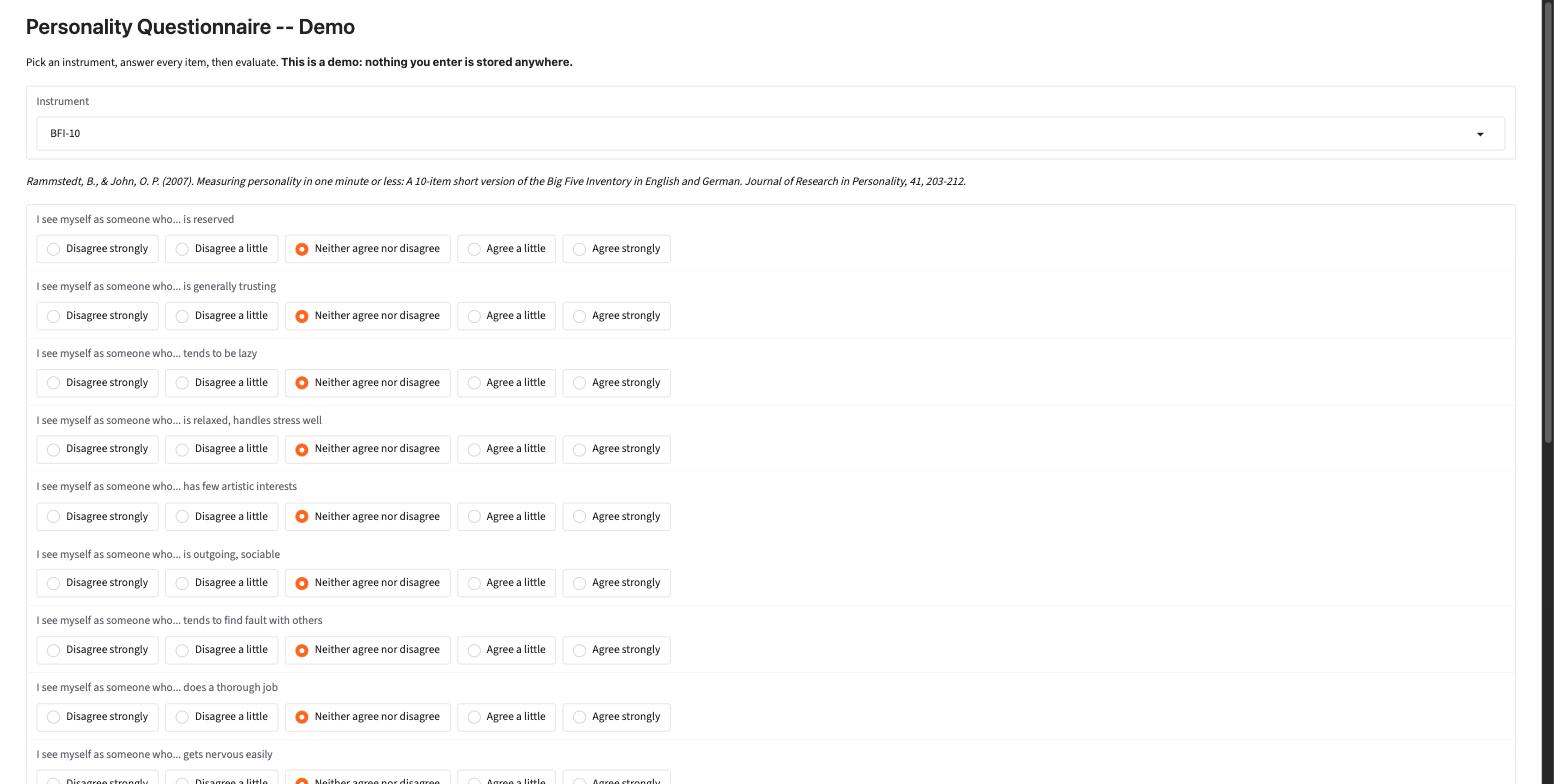
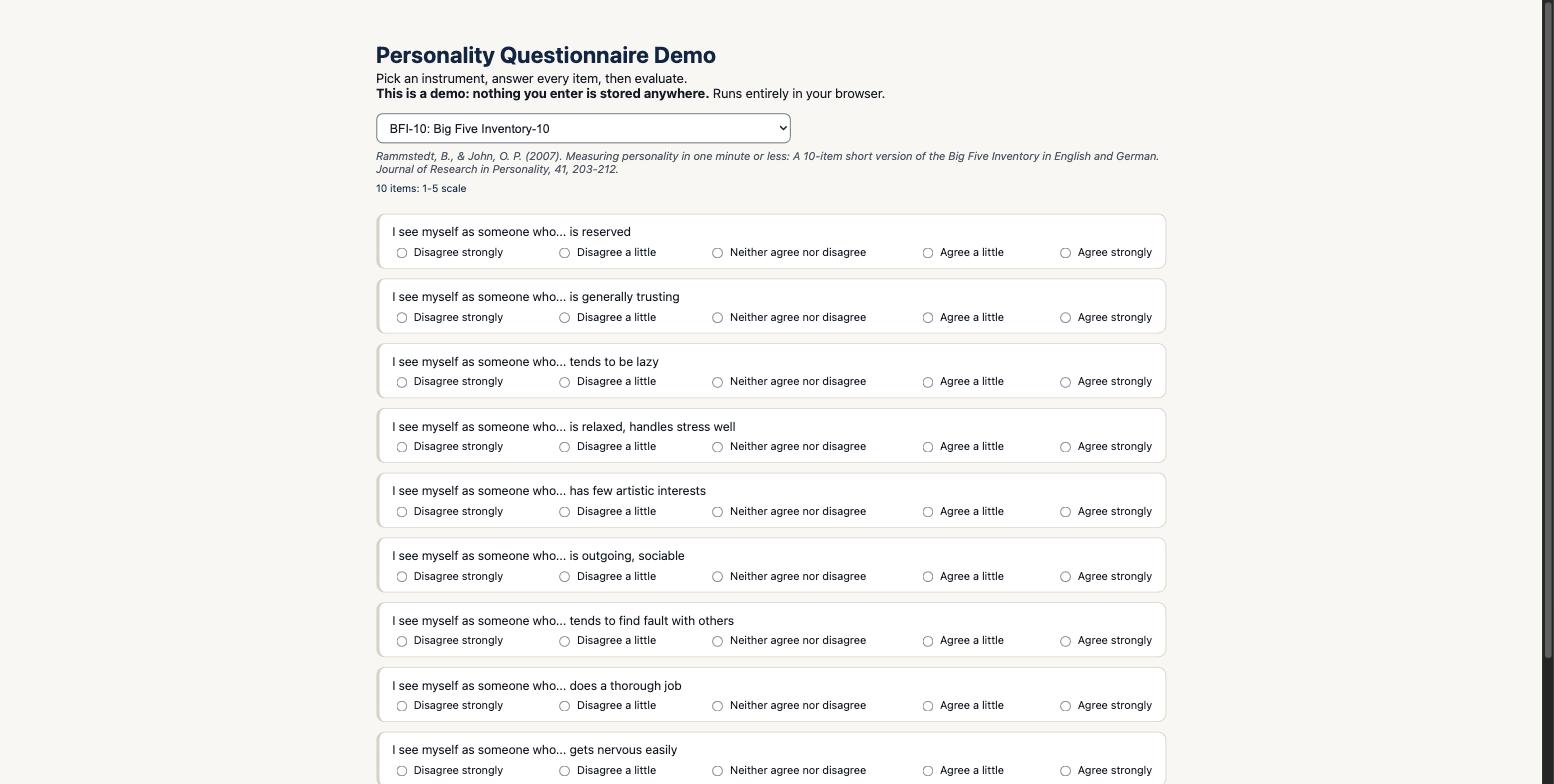
Gradio demo (left) and React/TypeScript demo (right), both scoring the same BFI-10 responses.
Both are deployable to Hugging Face Spaces (make push-space for the Docker
Gradio Space, make push-space-react for the static React Space), and both
paths are implemented and tested. Deployment is currently on hold: as of
2026-09, Hugging Face requires billing credits on the account to run a
Space’s build step, even on the nominally-free static SDK tier, so neither
Space is published right now. Once credits are added (or the React Space is
switched to shipping a pre-built dist/ with no build step), either make
target above publishes it.
How it works
flowchart LR
    I["instruments/<br/><i>pure data</i>"] --> R[registry]
    R --> S["scoring<br/><i>one vectorised scorer</i>"]
    S --> C[cli]
    S --> D[db]
    S --> U[ui]
Module |
Responsibility |
|---|---|
|
|
|
One module per questionnaire. Data only, no arithmetic |
|
The single scorer: reverse-keying, subscale means, normalisation, pre/post deltas |
|
Reading and writing responses and scores |
|
Package version, git SHA, instrument hash for each record |
|
SQLAlchemy record store, and the JSON/wide/long export shapes |
|
Theme tokens, runtime settings, and the application’s state |
|
The localhost data-collection application |
|
|
Design decisions
Instruments are Python literals, not data files. A literal is checked by the type
checker, validated at import, and present in the wheel by construction. A shipped CSV
is checked by nothing until a participant has already answered every item — and the
two scale files this repo used to carry were never read by any code path and
misspelled neuroticism, which is exactly how unread data drifts.
Reverse-keying belongs to the subscale, not the item. The VAS-F scores its five
energy items forward in Energy and reversed in Fatigue (composite), so a per-item
mask cannot express both. The reflection is folded into a signed weight matrix, which
also means every subscale at every level is computed by one matrix multiplication.
Both hierarchy levels are declared flat. The BFI-2’s five domains and fifteen facets are siblings, each listing its own item numbers, rather than domains being composed from facets. The arithmetic is identical and the flat form scores both levels in a single pass.
Polarity is recorded as data. Every subscale carries a higher_is string, so no
consumer has to infer direction from a name — the inference that produced the bug
below.
Development
make dev          # install everything
make fix          # format and autofix
make check        # lint, type-check, test, docs -- mirrors CI
make check-ci     # the same, in a throwaway venv built like CI's
Tests are unittest under coverage, mirroring the package layout in tests/.
Citation
@software{fodor_personality_questionnaire,
  author = {Fodor, Ádám},
  title  = {personality_questionnaire: administering and scoring validated psychometric instruments},
  url    = {https://github.com/fodorad/personality_questionnaire},
}
Contact
Ádám Fodor (fodorad201@gmail.com) — adamfodor.com